
A site publishing “Best Cases for the Galaxy Z Flip8” one week and “Best Screen Protectors for the Pixel 11 Pro” the next is running a content operation with a specific rhythm: a new flagship launches, and within days a dozen accessory roundups need to exist, each one grounded in something more useful than a manufacturer spec sheet. The actual research for a good roundup — does this case add noticeable bulk, does this screen protector actually survive a drop test, does this magnetic mount hold at highway speed — usually lives in accessory-review and durability-test videos on YouTube long before it shows up in a written article.
That's a research bottleneck that compounds with publishing volume. Watching a dozen five-to-ten-minute accessory videos to extract the handful of specific claims worth citing takes real time, and doing it fast enough to have a roundup live within days of a phone launch means something has to give — usually either the depth of the research or the time spent writing it up carefully.
Getting the specific claim out of the video without rewatching it
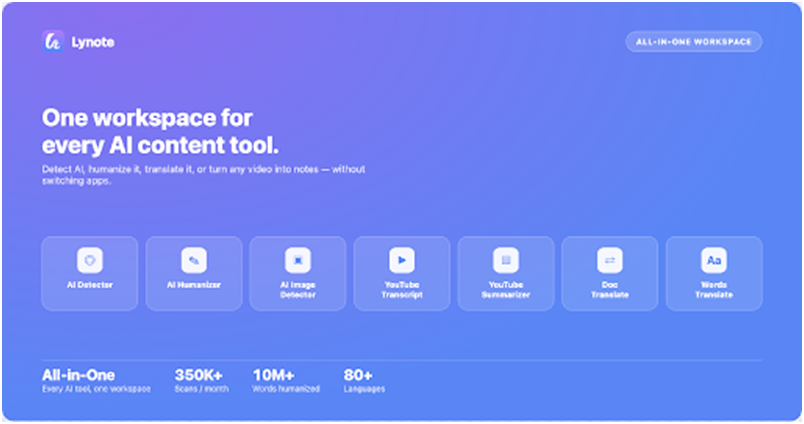
This is squarely the kind of task a transcript tool removes friction from. Lynote's youtube video transcript tool at lynote.ai/youtube-transcript converts a video into full, timestamped text, and supports pulling from multiple videos in one workflow rather than one link at a time — relevant when a single roundup might draw on five or six different accessory-review channels covering the same case or protector.
Instead of rewatching a ten-minute drop-test video to confirm exactly what a reviewer said about a case surviving a chest-height drop, the transcript makes that claim searchable text with a timestamp attached — useful both for writing the roundup accurately and for linking back to the specific moment if a reader wants to verify the claim themselves.
Why roundup content is especially exposed to the “sounds generic” problem
Accessory roundups have a structural weakness that straight news coverage doesn't: they're often written to a template — five products, a short paragraph each, a comparison table — which is exactly the kind of formulaic structure that starts to blur into generic AI-sounding prose if the writing process leans too heavily on speed. A reader comparing five near-identical paragraphs about five different phone cases can tell almost immediately when none of them contain a specific, testable claim, and that's also often the exact pattern an AI detector is built to flag.
Running a draft through a detector before it goes live catches that specific failure mode before a reader does. Lynote's free ai detector analyzes rhythm, repetition, lexical variance, and predictability at the sentence level instead of returning one score for a whole page, showing exactly which paragraphs read as AI-written, AI-edited, or mixed — which for a roundup usually means flagging the one generic-sounding product blurb that never actually mentions a specific test result, buried among four other paragraphs that do.
There's no sign-up wall for a quick check, which matters for a workflow where a dozen product blurbs might need checking on a tight publishing deadline, and the tool doesn't use submitted text to train its own models — relevant for anything checked before it's live anywhere.
The same problem shows up outside accessory roundups too
This isn't limited to case-and-protector content. A lot of the same production pressure applies to “everything we know so far” launch-roundup articles and ongoing news coverage published at a similar pace, where a writer is often working from several video sources — a leak channel, an official teaser, a hands-on from a launch event — to assemble one coherent piece under a tight deadline. The research-then-check workflow described above scales the same way regardless of whether the finished piece is a five-product buying guide or a running news post, because the underlying bottleneck is identical: pulling accurate claims out of video sources quickly, then making sure the writing that results still reads as specific rather than templated once it's assembled under time pressure.
It's also worth separating what a detector check is actually for here from what it isn't. It's not a test of whether a writer used AI assistance at any point in drafting — plenty of legitimate, well-researched roundups get outlined or organized with AI help and then get filled in with real, tested detail by the person who actually used the product. The check exists to catch the narrower, more common failure: a blurb where the specific detail got smoothed away into generic phrasing somewhere between the transcript and the final draft, usually because a deadline didn't leave time for a careful pass. Catching that in two minutes before publishing is a much cheaper fix than a reader noticing it first and assuming the whole roundup wasn't actually tested.
Where this actually saves time on a publishing schedule
The two tools solve adjacent parts of the same production problem rather than the same problem twice. The transcript tool speeds up the research phase — getting from “watch a dozen videos” to “search a dozen transcripts” for the handful of claims that actually matter. The detector speeds up the editing phase — catching which specific paragraphs need a real detail added back in under two minutes, instead of a slower manual read-through of an entire roundup hoping to spot the weak section by feel.
For a content operation built around being fast after every major launch, without publishing roundups that all start to read the same, that combination fits the actual production schedule better than either tool would on its own. Readers comparing cases or screen protectors are ultimately trying to answer one question per product — is this specific claim true — and a roundup that visibly answers it, rather than gesturing at it in template language, is the one that keeps them coming back for the next phone's roundup too, and the one worth clicking through from search instead of the next near-identical result.